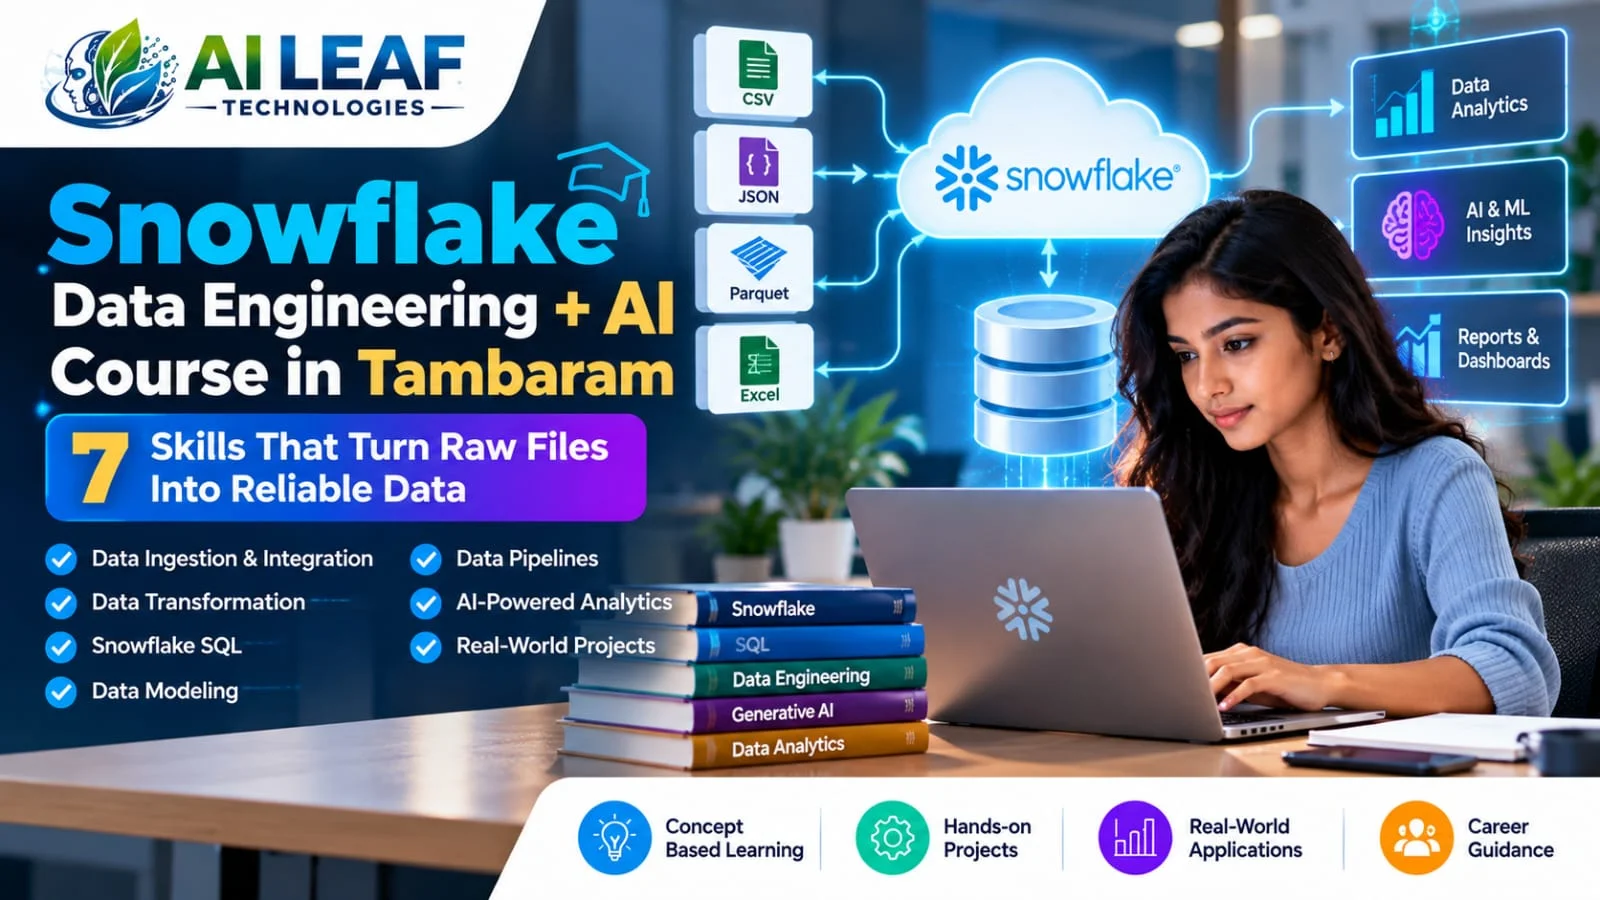
𝗦𝗻𝗼𝘄𝗳𝗹𝗮𝗸𝗲 𝗗𝗮𝘁𝗮 𝗘𝗻𝗴𝗶𝗻𝗲𝗲𝗿𝗶𝗻𝗴 +𝗔𝗜 𝗖𝗼𝘂𝗿𝘀𝗲 𝗶𝗻 𝗧𝗮𝗺𝗯𝗮𝗿𝗮𝗺: 𝟳 𝗦𝗸𝗶𝗹𝗹𝘀 𝗧𝗵𝗮𝘁 𝗧𝘂𝗿𝗻 𝗥𝗮𝘄 𝗙𝗶𝗹𝗲𝘀 𝗜𝗻𝘁𝗼 𝗥𝗲𝗹𝗶𝗮𝗯𝗹𝗲 𝗗𝗮𝘁𝗮
- Introduction: The Real Job of a Data Engineer
- Seven Practical Skills to Develop
- How AI Helps a Snowflake Engineer
- A Portfolio Project: Grocery Delivery Orders Pipeline
- Getting Ready for Data Engineering Interviews
- Choosing a Snowflake Data Engineering +AI Course in Tambaram
- Snowflake Training at AI Leaf Technologies
- Conclusion
- Frequently Asked Questions
𝗧𝗵𝗲 𝗥𝗲𝗮𝗹 𝗝𝗼𝗯 𝗼𝗳 𝗮 𝗗𝗮𝘁𝗮 𝗘𝗻𝗴𝗶𝗻𝗲𝗲𝗿
A Snowflake Data Engineering +AI Course in Tambaram should teach you one thing above all: how to move messy files into clean, trustworthy tables without anyone repairing them by hand every morning. Tool names change every few years, but that reliability is what companies pay a data engineer for.
Picture an online grocery service with several delivery branches. Each night, every branch sends files for orders, refunds and rider trips. By nine the next morning, the manager expects one dashboard that matches reality. Someone has to collect those files, load them, check them, combine them and deal with the day a branch sends a broken file. That person is the data engineer.
Snowflake is a popular platform for this work because it keeps storage and computing power separate and runs on the cloud, so teams can grow without buying servers. AI tools now help with writing and explaining code, but they do not remove the need to understand the pipeline. The seven skills below show what to learn and how to test whether a course really teaches it.
𝗦𝗲𝘃𝗲𝗻 𝗣𝗿𝗮𝗰𝘁𝗶𝗰𝗮𝗹 𝗦𝗸𝗶𝗹𝗹𝘀 𝘁𝗼 𝗗𝗲𝘃𝗲𝗹𝗼𝗽
𝗦𝗸𝗶𝗹𝗹 𝟭: 𝗨𝗻𝗱𝗲𝗿𝘀𝘁𝗮𝗻𝗱 𝗛𝗼𝘄 𝗦𝗻𝗼𝘄𝗳𝗹𝗮𝗸𝗲 𝗜𝘀 𝗕𝘂𝗶𝗹𝘁
Snowflake separates three things: storage, which holds your tables; virtual warehouses, which are the compute engines that run queries; and a services layer that handles security, metadata and optimisation.
That split has practical effects. Two teams can query the same data on different warehouses without slowing each other, and a warehouse can be resized or paused when idle. Run one query on a small warehouse and again on a larger one, and note both the time and the credits used.
𝗦𝗸𝗶𝗹𝗹 𝟮: 𝗢𝗿𝗴𝗮𝗻𝗶𝘀𝗲 𝗗𝗮𝘁𝗮𝗯𝗮𝘀𝗲𝘀, 𝗦𝗰𝗵𝗲𝗺𝗮𝘀 𝗮𝗻𝗱 𝗥𝗼𝗹𝗲𝘀
Data lives in databases, which are divided into schemas, which hold tables. A tidy layout, such as separate raw, staging and reporting schemas, tells every colleague where a table sits in the journey from file to dashboard.
Roles decide who may see or change what. Give analysts access to the reporting schema only, and keep write access for the pipeline. Working this way from your first practice session builds a habit that employers notice.
𝗦𝗸𝗶𝗹𝗹 𝟯: 𝗟𝗼𝗮𝗱 𝗙𝗶𝗹𝗲𝘀 𝗧𝗵𝗿𝗼𝘂𝗴𝗵 𝗦𝘁𝗮𝗴𝗲𝘀, 𝗖𝗢𝗣𝗬 𝗮𝗻𝗱 𝗦𝗻𝗼𝘄𝗽𝗶𝗽𝗲
A stage is a holding area for files, and a file format tells Snowflake how to read them, whether CSV or JSON. The COPY INTO command then moves the contents into a table in one controlled step.
For files that keep arriving through the day, Snowpipe loads them automatically as they land instead of waiting for a nightly batch. Practise with a deliberately broken file, learn the options for skipping or stopping on bad rows, and read the load history to confirm no file was loaded twice.
𝗦𝗸𝗶𝗹𝗹 𝟰: 𝗣𝗿𝗼𝗰𝗲𝘀𝘀 𝗢𝗻𝗹𝘆 𝗪𝗵𝗮𝘁 𝗖𝗵𝗮𝗻𝗴𝗲𝗱 𝗪𝗶𝘁𝗵 𝗦𝘁𝗿𝗲𝗮𝗺𝘀 𝗮𝗻𝗱 𝗧𝗮𝘀𝗸𝘀
Reloading a whole table every night wastes time and money. A stream records which rows were inserted, updated or deleted since you last looked, so you can process only those.
A task runs a SQL statement on a schedule, or only when a stream has new data. Together they form an incremental pipeline. Test what happens if a task runs twice, because a safe pipeline gives the same result either way.
𝗦𝗸𝗶𝗹𝗹 𝟱: 𝗥𝗲𝗰𝗼𝘃𝗲𝗿 𝗠𝗶𝘀𝘁𝗮𝗸𝗲𝘀 𝗪𝗶𝘁𝗵 𝗧𝗶𝗺𝗲 𝗧𝗿𝗮𝘃𝗲𝗹 𝗮𝗻𝗱 𝗖𝗹𝗼𝗻𝗶𝗻𝗴
Everyone deletes the wrong rows eventually. Time Travel lets you query a table as it looked earlier, or restore something dropped by accident, within the retention period your account allows.
Cloning creates a copy of a table or schema without duplicating the stored data at that moment, which makes it a safe sandbox for testing a risky change. Practise deleting rows on purpose and bringing them back so the steps feel familiar before a real emergency.
𝗦𝗸𝗶𝗹𝗹 𝟲: 𝗞𝗲𝗲𝗽 𝗤𝘂𝗲𝗿𝗶𝗲𝘀 𝗙𝗮𝘀𝘁 𝗮𝗻𝗱 𝗖𝗼𝘀𝘁𝘀 𝗨𝗻𝗱𝗲𝗿 𝗖𝗼𝗻𝘁𝗿𝗼𝗹
In Snowflake, running compute costs credits, so careless queries cost money. The query profile shows where time went, and warehouse size, auto-suspend settings and sensible filtering all influence the bill.
Compare the same query before and after a change, and write down the difference. A candidate who can say “this query was cut from forty seconds to six by pruning on the date column” sounds far more credible than one who only knows definitions.
𝗦𝗸𝗶𝗹𝗹 𝟳: 𝗨𝘀𝗲 𝗔𝗜 𝗮𝘀 𝗮 𝗛𝗲𝗹𝗽𝗲𝗿 𝗬𝗼𝘂 𝗔𝗹𝘄𝗮𝘆𝘀 𝗩𝗲𝗿𝗶𝗳𝘆
AI assistants can explain a long unfamiliar query, suggest a transformation or draft documentation for a pipeline. They can also assume your data has no duplicates, join on the wrong key or write a query that scans far more data than needed.
Check every draft on a small table whose correct answer you can calculate yourself, and review it for cost before running it on large data. Keep customer information out of public AI tools unless your employer has approved them.
𝗛𝗼𝘄 𝗔𝗜 𝗛𝗲𝗹𝗽𝘀 𝗮 𝗦𝗻𝗼𝘄𝗳𝗹𝗮𝗸𝗲 𝗘𝗻𝗴𝗶𝗻𝗲𝗲𝗿
A large part of the job is routine: writing similar transformations, preparing test rows, documenting steps and reading code someone else wrote. AI can shorten each of these, especially when you give it your real table definitions rather than a vague description.
It still cannot know that a branch sends refunds as negative numbers, or that one file was loaded twice last month. Business context has to come from you. Snowflake also provides AI-related features of its own, so read the current Snowflake documentation to see what your account supports before relying on any of them.
𝗔 𝗣𝗼𝗿𝘁𝗳𝗼𝗹𝗶𝗼 𝗣𝗿𝗼𝗷𝗲𝗰𝘁: 𝗚𝗿𝗼𝗰𝗲𝗿𝘆 𝗗𝗲𝗹𝗶𝘃𝗲𝗿𝘆 𝗢𝗿𝗱𝗲𝗿𝘀 𝗣𝗶𝗽𝗲𝗹𝗶𝗻𝗲
Build a small pipeline for an imaginary grocery delivery service. Create sample CSV files for orders and refunds, upload them to a stage, load them into a raw table with COPY INTO and add a stream on that table.
Then create a task that updates a daily sales summary from the stream, simulate a mistaken delete and recover it with Time Travel, and test your changes on a clone first. Finish with a short write-up covering your schema design, test results, estimated credit use, weak points and the places where AI helped and how you checked it. Use invented data only. A project like this gives interviewers concrete material to question, though it does not promise a job.
𝗚𝗲𝘁𝘁𝗶𝗻𝗴 𝗥𝗲𝗮𝗱𝘆 𝗳𝗼𝗿 𝗗𝗮𝘁𝗮 𝗘𝗻𝗴𝗶𝗻𝗲𝗲𝗿𝗶𝗻𝗴 𝗜𝗻𝘁𝗲𝗿𝘃𝗶𝗲𝘄𝘀
Interviewers for Snowflake roles usually begin with concepts: what a virtual warehouse is, how a stage differs from a table, when Snowpipe is a better choice than COPY, and what Time Travel allows. Then they ask you to explain a pipeline you built.
Strong SQL underpins all of it. If yours needs work, a focused programme such as Oracle SQL and PL/SQL training can build the habit of writing and checking queries. If you also want Python, Spark and wider cloud pipelines, compare Snowflake with the broader AI-powered data engineering course. Roles to look at include Snowflake developer, data engineer, ETL developer and analytics engineer.
𝗖𝗵𝗼𝗼𝘀𝗶𝗻𝗴 𝗮 𝗦𝗻𝗼𝘄𝗳𝗹𝗮𝗸𝗲 𝗗𝗮𝘁𝗮 𝗘𝗻𝗴𝗶𝗻𝗲𝗲𝗿𝗶𝗻𝗴 +𝗔𝗜 𝗖𝗼𝘂𝗿𝘀𝗲 𝗶𝗻 𝗧𝗮𝗺𝗯𝗮𝗿𝗮𝗺
Put these questions to any institute, and expect specific answers rather than general promises:
* Will I load real files, break them on purpose and fix the pipeline myself?
* Are streams, tasks and Snowpipe covered with hands-on work, not only slides?
* How do you teach cost control and query tuning?
* How is AI used in class, and how is its output checked?
* Can I see fees, duration, batch timings and prerequisites in writing?
* What exactly does the placement support include?
Placement support usually means help with resumes, mock interviews and introductions, not a guaranteed job. Treat any promise of certain placement with caution.
𝗦𝗻𝗼𝘄𝗳𝗹𝗮𝗸𝗲 𝗧𝗿𝗮𝗶𝗻𝗶𝗻𝗴 𝗮𝘁 𝗔𝗜 𝗟𝗲𝗮𝗳 𝗧𝗲𝗰𝗵𝗻𝗼𝗹𝗼𝗴𝗶𝗲𝘀
According to its website, AI Leaf Technologies offers a Snowflake Data Engineering +AI programme covering Snowflake architecture, databases, schemas, warehouses, stages, file formats, data loading, Snowpipe, streams, tasks, Time Travel, cloning, performance optimisation and project workflows. The listed duration is 40 to 50 days, in online and offline modes, with placement support. It is described as suitable for SQL developers, data engineers, ETL professionals and analytics aspirants.
The institute is on Mudichur Road near Tambaram and also teaches live online classes across India. Details can change, so confirm the latest syllabus, fees and batch dates on the Snowflake course page or with the team.
𝗖𝗼𝗻𝗰𝗹𝘂𝘀𝗶𝗼𝗻
Choosing a Snowflake Data Engineering +AI Course in Tambaram comes down to a practical test: by the end, can you load files safely, process only what changed, recover from mistakes, keep costs sensible and use AI without trusting it blindly? The seven skills in this guide give you a way to check each of those promises.
Visit the institute, ask for sample exercises and compare more than one option. A course that lets you build and break real pipelines, and that describes its placement support honestly, deserves serious consideration. To ask about a free demo or the next batch, use the contact page.
What does a Snowflake Data Engineering +AI Course in Tambaram teach?
It generally covers Snowflake architecture, loading data, Snowpipe, streams, tasks, Time Travel, cloning and performance tuning, along with ways to use AI tools while working. Each institute's syllabus differs, so compare them.
Do I need to know SQL before joining?
Basic SQL helps a great deal because almost every Snowflake task uses it. Beginners should strengthen their SQL first or choose a course that covers it.
What is a virtual warehouse in Snowflake?
It is a compute resource that runs your queries and loads. You can resize it or pause it, and you pay for the time it is running.
What is the difference between COPY INTO and Snowpipe?
COPY INTO loads files when you run it, which suits scheduled batches. Snowpipe loads files automatically soon after they arrive in a stage.
What are Time Travel and cloning used for?
Time Travel lets you view or restore earlier versions of data within a retention window. Cloning makes a quick copy for testing without duplicating the stored data at once.
Can freshers become Snowflake data engineers?
Freshers can start, but they usually need solid SQL and at least a few finished projects. Entry roles vary between employers.
Can AI replace a data engineer?
AI can speed up routine coding and documentation, but people still design pipelines, verify results and take responsibility for data quality.
Will the course guarantee me a job?
No training can promise that. Your skills, projects, communication and the openings available at the time all affect the result.